Dynamic Checkpoint Architectures Face Latency Divergence
Dynamic checkpoint architectures preserve reliability across distributed frameworks as transport latency divergence disrupts consensus control.
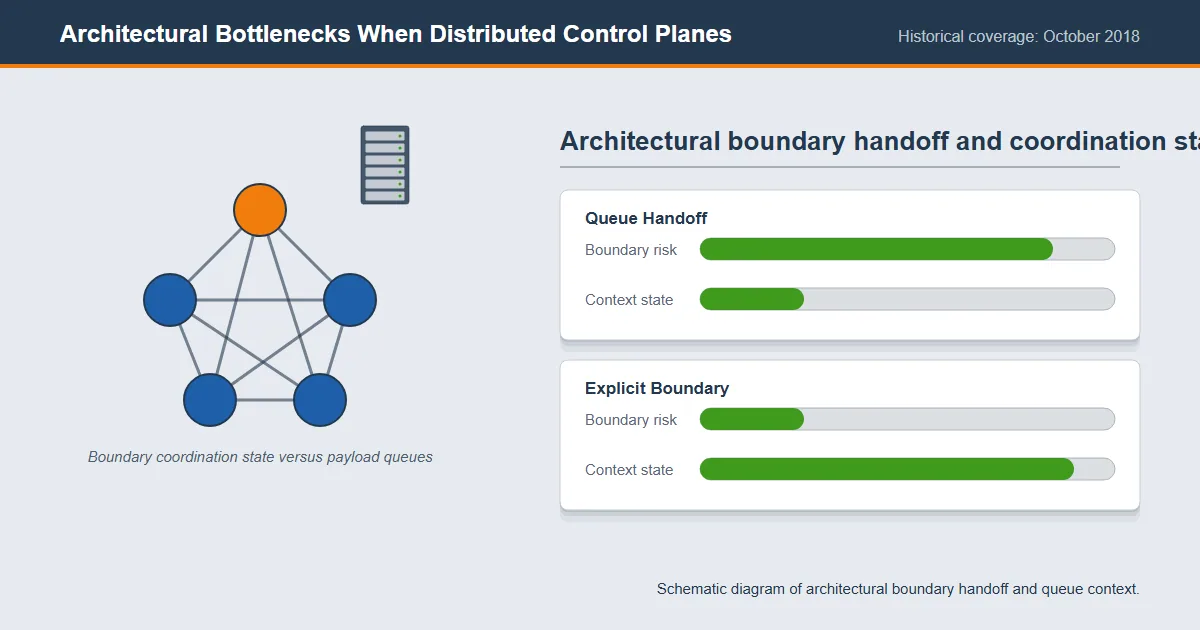
As of October 31, 2018, dynamic checkpoint architectures preserve reliability when distributed nodes face network transport latency divergence, preventing static timeout thresholds from triggering spurious leader re-elections.
During October 2018, distributed infrastructure designs increasingly confront harsh physical boundaries as high-level control software attempts to run across diverse, variable communication topologies. As documented by recent engineering investigations (IEEE), the adoption of dynamic checkpoint architectures on distributed frameworks represents a critical milestone for preserving reliability when distributed nodes face network transport latency divergence. When software frameworks treat the network as an idealized fabric with negligible transit delays, transient packet stalls rapidly cascade into systemic deadlocks. This friction prompts an essential operational question:
How Does Transport Latency Degrade Consensus Control?
The adoption of dynamic checkpoint architectures on distributed frameworks represents a critical milestone for preserving reliability when distributed nodes face network transport latency divergence (IEEE). Structuring complex event processing as microservices in distributed smart city deployments signifies a major architectural transition to scale asynchronous event streams under real-world network transport constraints (IEEE). Dynamic checkpointing frameworks and microservices-based event processing systems both require synchronous coordination assumptions across distributed nodes to avoid operational state inconsistency (SAGE Publications). Distributed automation architectures integrate LoRa wireless technology with the Message Queue Telemetry Transfer protocol to manage asynchronous messaging across constrained network environments (IEEE). Distributed data acquisition architectures for magnetic positioning systems rely on synchronized sensor node networks to ensure positional tracking data integrity (IEEE). Reliability mechanisms in distributed control and messaging architectures, such as dynamic checkpointing and telemetry queuing, must accommodate the latency characteristics of underlying transport layers (IEEE). The operational breakdown begins at the boundary between deterministic software state machines and non-deterministic physical media. In local server racks, low-latency interconnects permit consensus engines to exchange heartbeat frames and commit logs with negligible round-trip times. However, expanding these topologies across wide-area links or congested edge fabrics shatters that operational comfort. As investigated in distributed consensus and failure recovery research (IEEE), the adoption of dynamic checkpoint architectures on distributed frameworks represents a critical milestone for preserving reliability when distributed nodes face network transport latency divergence. Without adaptive checkpoint mechanisms, static timeout thresholds misclassify delayed packets as node failures, triggering spurious leader re-elections and consensus thrashing. The coordination plane spends more computational budget renegotiating cluster membership than advancing user workloads, demonstrating how transport latency directly degrades control throughput. This failure mode compounds when control algorithms presume that all nodes observe state mutations in monotonic, simultaneous intervals. When network transport guarantees degrade, distributed nodes experience significant clock drift, queue buildup, and variable packet flight times. Under these conditions, serial execution models fail because read and write barriers stall waiting for remote confirmations that sit trapped in physical transmission queues. If the control tier attempts to bypass these waits through unverified local state assertions, split-brain conditions arise, leaving independent worker nodes with conflicting views of valid operational state. System throughput drops precipitously as retransmission storms saturate the remaining transport bandwidth, turning localized transit jitter into total control plane paralysis.
Why Must Messaging Protocols Match Physical Media?
Architectural partitioning demands a rigorous separation between high-frequency control messages and data payload conduits. Nevertheless, such decomposed architectures encounter severe fragility when message routing rules depend on tightly synchronized registries. If an event-routing microservice processes incoming state alterations before upstream policy synchronizations conclude, message delivery guarantees fail, resulting in out-of-order execution and phantom event drops. Mitigating these transport limits requires matching messaging protocols explicitly to the underlying physical transmission properties. For example, distributed automation architectures integrate LoRa wireless technology with the Message Queue Telemetry Transfer protocol to manage asynchronous messaging across constrained network environments (SAGE Publications). In such low-power, long-range wireless links, strict synchronous handshakes become completely impractical due to duty-cycle restrictions and low data rates. Instead, the control layer must decouple transport-level acknowledgment from application-level execution using topic-based broker topologies. By buffering updates through lightweight publish-subscribe protocols, distributed controllers can gracefully absorb transmission latency rather than stalling upstream state machines while waiting for physical link availability. High-precision tracking frameworks provide another clear demonstration of these transport dependencies. When sensor nodes sample magnetic fields across wide spatial matrices, unsynchronized reporting introduces spatial skew, corrupting positioning calculations. Consequently, reliability mechanisms in distributed control and messaging architectures, such as dynamic checkpointing and telemetry queuing, must accommodate the latency characteristics of underlying transport layers (IEEE; SAGE Publications). System architects must reject the assumption of uniform transport guarantees and instead build coordination models that explicitly account for message latency, jitter, and transport constraints across all operational boundaries.
Can Future Distributed Frameworks Adapt Coordination Guarantees?
By October 2018, distributed systems engineering confirms that assuming zero-latency state synchronization across physically dispersed nodes is unsustainable. When transport realities are ignored, control layers inevitably collapse under timeout cascades and partition loops. Engineers must treat transport latencies as primary architectural constraints rather than low-level implementation details. This leaves open a critical architectural question: Can future distributed frameworks dynamically adapt their coordination guarantees to fluctuating network latencies without sacrificing strict operational consistency?
Sources
- IEEE: Dynamic Checkpoint Architecture for Reliability Improvement on Distributed Frameworks, 2018-10-08
- IEEE: A Microservices Architecture for Distributed Complex Event Processing in Smart Cities, 2018-10-11
- SAGE Publications: A home automation architecture based on LoRa technology and Message Queue Telemetry Transfer protocol, 2018-10-17
- IEEE: A Distributed Data Acquisition Architecture for Magnetic Positioning Systems, 2018-10-17